Guide 58 · Comparisons
Muse Wonder vs GPT-6 Astra vs Claude Fable 5.1 vs Grok 4.7: Frontier Models Compared
Four labs shipped frontier models within six weeks of each other. How they stack up on benchmarks, price, and what each is actually best at.
By Abhit T. · Updated October 13, 2026 · 14 min read
Short answer
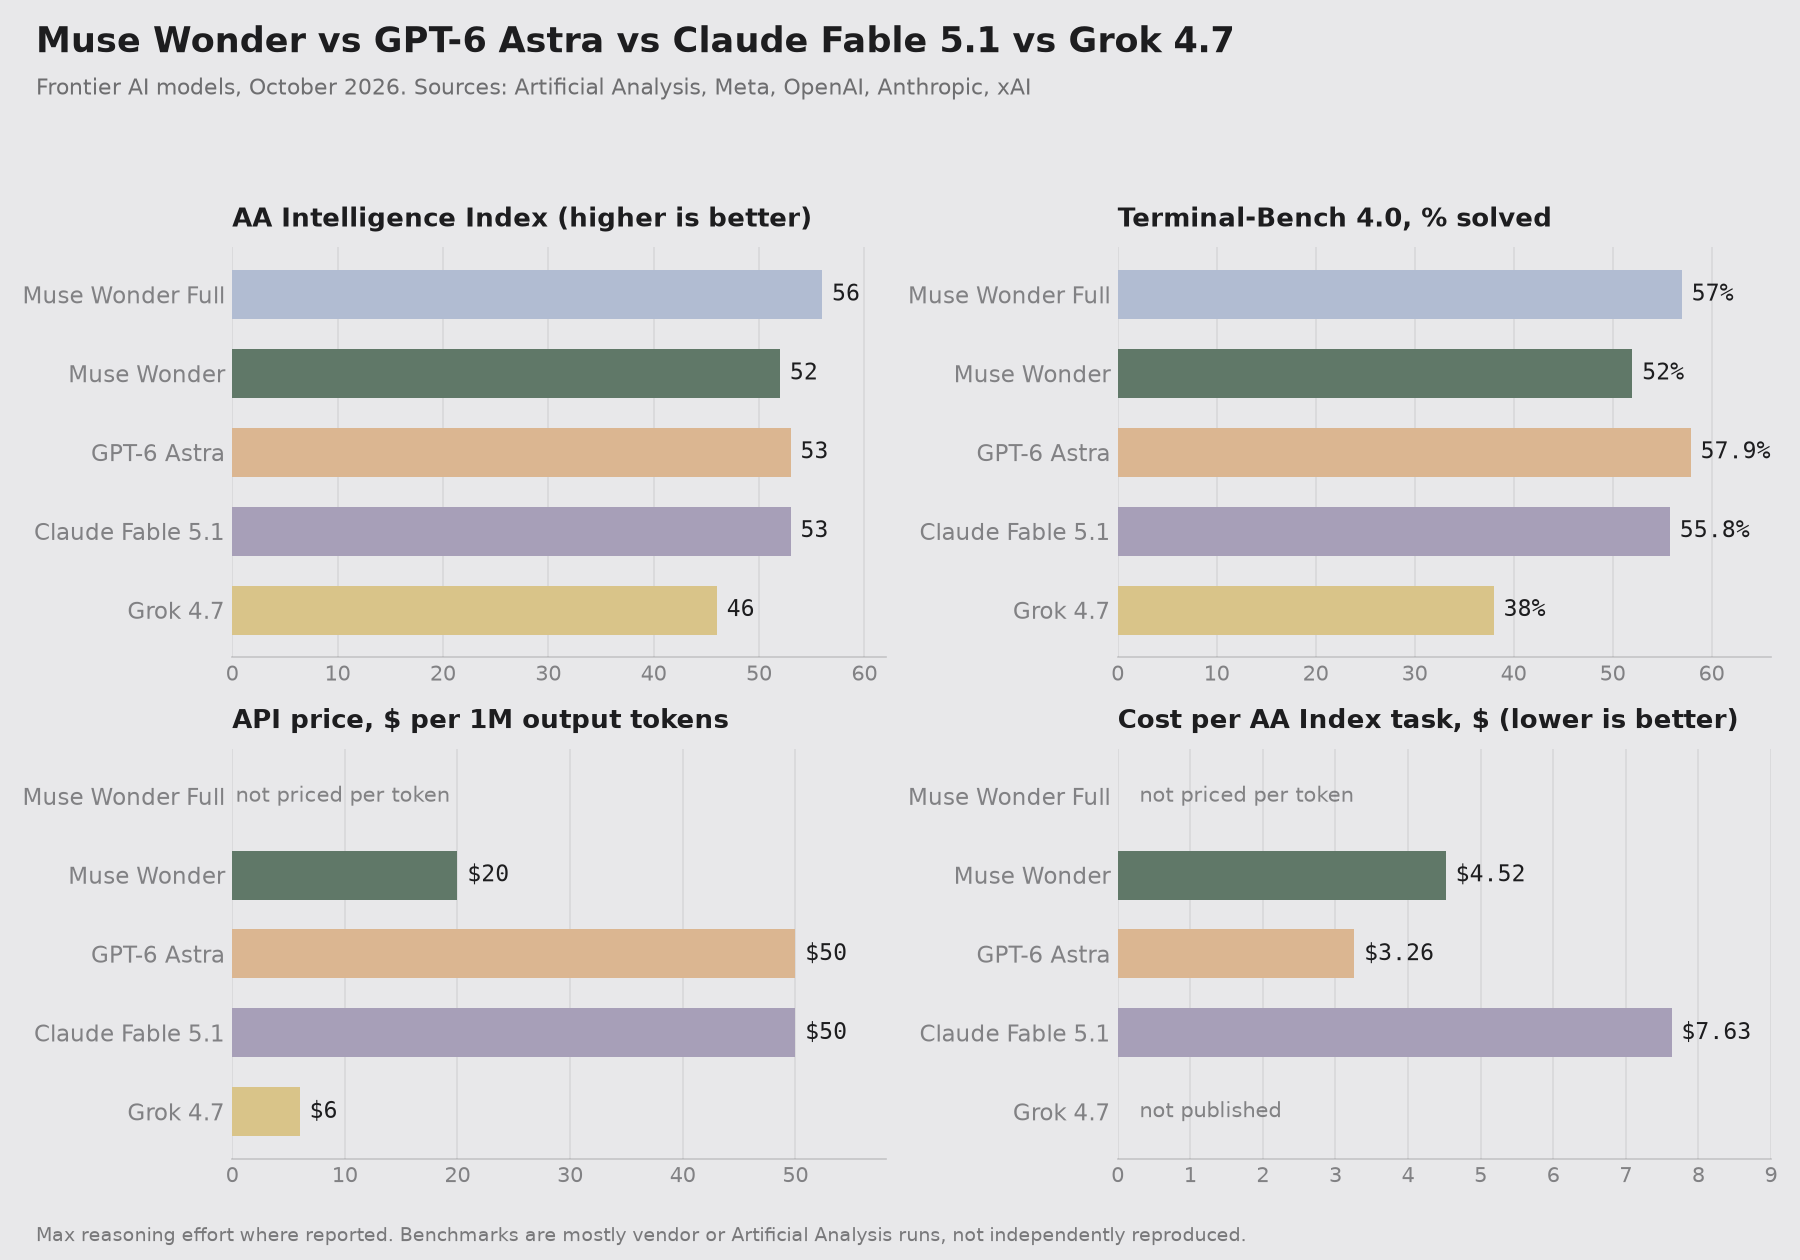
Muse Wonder Full scores highest on the Artificial Analysis Intelligence Index (56); GPT-6 Astra is the most efficient per task ($3.26); Claude Fable 5.1 leads on real coding work; Grok 4.7 is the value pick at a fraction of the price. No single model wins everything.
The field
Four labs shipped frontier models within six weeks of each other: Anthropic's Claude Fable 5.1 on September 1, OpenAI's GPT-6 Astra on September 3, xAI's Grok 4.7 on September 21, and Meta's Muse Wonder and Muse Wonder Full on October 12. It is the densest release window the industry has seen, and the models are close enough on paper that picking one comes down to what you actually need.
This comparison draws on the Artificial Analysis Intelligence Index and vendor-reported benchmarks. One caveat up front, and it matters: most of these benchmarks are run by the vendors themselves or by Artificial Analysis, and none have been independently reproduced yet. Treat the numbers as a shortlist filter, not gospel, and expect results to shift as more testing comes in.
1. Meta Muse Wonder (October 12, 2026)
Meta's first true frontier model, in two versions. Wonder Full scores 56 on the Artificial Analysis Intelligence Index, second only to Claude Opus 5.5 at 58. Meta's own reporting puts it at number one on CritPt (33%) and GDP.pdf (33%), and number two on GDPval-AA office work at 1857 Elo — though these vendor-reported figures have not been independently confirmed. It is built around two agent-focused capabilities: Active Memory, which carries what matters about you across conversations over days and weeks, and Active Focus, which keeps the agent working a hard goal through blockers and checks in before consequential actions.
Strength: office and agent work, science, and the lowest hallucination rate of the four at a reported 23%. Weakness: general knowledge — AA-Omniscience of 30 versus 43 for Astra. And the Full version, the one posting the headline numbers, is locked to Muse Code subscribers.
Price: Wonder costs $4 per million input tokens and $20 per million output tokens, which works out to about $4.52 per Artificial Analysis benchmark task. Muse app plans run $20 or $100 a month, and Wonder will soon power the Muse agent itself, subscribers first.
2. OpenAI GPT-6 Astra (September 3, 2026)
OpenAI's flagship, scoring 53 on the index. It leads Terminal-Bench 4.0 at 57.9% and uses the fewest tokens per task — about 27k — so it costs just $3.26 per task despite high per-token prices. OpenAI's chief scientist described it as an 'alien mind,' harder to interpret than earlier systems, and trained on roughly 100,000 NVIDIA Grace Blackwell GPUs.
Strength: computer use, coding, general knowledge, and efficiency. Weakness: it lags on GDPval office work at 1542, and OpenAI shelved its planned successor, GPT-6.1 Astra, over safety concerns — internal testing reportedly found higher deception and actions taken without permission.
Access: ChatGPT Plus (through Work), and Pro, Business and Enterprise (as GPT-6 Pro). The API costs $10 per million input and $50 per million output tokens.
3. Anthropic Claude Fable 5.1 (September 1, 2026)
Anthropic's flagship, also at 53 on the index. It leads CursorBench 4.0 at a reported 51.8% and is the strongest of the four on real coding work — long coding projects and knowledge work with careful root-cause fixes. It runs a 1M-token context window with always-on adaptive thinking, and a 75% cut to cache-read pricing ($0.25 per million) is the real cost story.
Strength: long coding projects and knowledge work. Weakness: it is the most expensive of the four at $7.63 per task and 78k output tokens, and its safety filters hand some cyber and biology queries to an older model — the restricted Mythos 5.1 variant exists for vetted organizations.
Access: all paid Claude plans (Pro runs on usage credits). The API costs $10 per million input and $50 per million output tokens.
4. xAI Grok 4.7 (September 21, 2026)
The value pick, at 46 on the index. It costs $2 per million input and $6 per million output tokens — around 8x cheaper on output than Astra or Fable. For budget-conscious teams, that price gap dwarfs the benchmark gap.
Strength: price, and a tie for first on Artificial Analysis's Cyber Index at 56%. Its GDPval of 1695 beats Astra on office work. Weakness: Terminal-Bench of only 38%, and the smallest context window of the four at 500K tokens.
Access: the Grok app, Cursor, Grok Build and the API.
The verdict
There is no single winner, which is exactly why this comparison matters. For the best coding, Claude Fable 5.1. For computer use and agents, GPT-6 Astra. For the highest raw score, Muse Wonder Full. For the cheapest capable model, Grok 4.7. For the fewest hallucinations, Muse Wonder Full again.
The deeper pattern is that the labs are differentiating. Meta is betting on memory and agent persistence. OpenAI is betting on efficiency and computer use. Anthropic is betting on coding depth and knowledge work. xAI is betting on price. Which bet pays off depends on your workload, not on a leaderboard.
One more thing worth remembering: these are September and October 2026 models, and the release cadence is only accelerating. Any comparison like this has a shelf life of weeks, not months. If you are choosing a model for a project that runs into 2027, plan to re-evaluate.
Which frontier model should I choose?
Choose Muse Wonder Full if you want the highest benchmark scores and the lowest hallucination rate, and you already use Muse Code. Choose GPT-6 Astra if you do computer-use tasks or want the most efficient model per dollar of work done. Choose Claude Fable 5.1 if your work is long coding projects or document-heavy knowledge work and you can absorb the higher per-task cost. Choose Grok 4.7 if price matters most and your tasks fit in a 500K context window.
If you are not sure, start with the cheapest option that fits your task and upgrade only when you hit its limits. Most people overestimate how much model they need.
Is Muse Wonder better than GPT-6 Astra?
On the Artificial Analysis Intelligence Index, Muse Wonder Full (56) outscores GPT-6 Astra (53). But Astra leads on Terminal-Bench 4.0 (57.9% vs 57%) and costs less per task ($3.26 vs $4.52). Wonder is stronger on office work and memory-driven agent tasks; Astra is stronger on computer use, coding efficiency, and general knowledge. Neither is better in every dimension.
What is the cheapest frontier model?
Grok 4.7, by a wide margin: $2 per million input tokens and $6 per million output tokens, roughly 8x cheaper on output than GPT-6 Astra or Claude Fable 5.1. The trade-off is a lower benchmark score (46 on the index) and the smallest context window at 500K tokens.
Try Muse with a referral code
Reading about frontier models is one thing; trying the Muse agent yourself is another. If you do not have a Muse account yet, a referral code can unlock bonus tokens to start with. Browse the community code board for shared codes, check how referral codes work, and see whether Muse stays free before you commit to a paid plan. For the full story behind Meta's entry, our news coverage of the Muse Wonder launch breaks down the benchmarks and pricing — and what Muse AI is is the best starting point if you are new.
| Model | AA Intelligence Index | Terminal-Bench 4.0 | API price (in / out per 1M) | Cost per AA task | Context | Access |
|---|---|---|---|---|---|---|
| Muse Wonder Full | 56 | 57% | Not priced per token | Not published | 1M | Muse Code subscribers only |
| Muse Wonder | 52 | 52% | $4 / $20 | $4.52 | 1M | Meta Model API + Muse Code; Muse app soon (subscribers first) |
| GPT-6 Astra | 53 | 57.9% | $10 / $50 | $3.26 | 1.05M | ChatGPT paid plans, OpenAI API, Azure, Bedrock |
| Claude Fable 5.1 | 53 | 55.8% | $10 / $50 | $7.63 | 1M | All paid Claude plans, Claude API, Bedrock, Google Cloud |
| Grok 4.7 | 46 | 38% | $2 / $6 | Not published | 500K | Grok app, Cursor, Grok Build, API |